Ahrefs Domain Rating set in type 2 Nov 2026, reset 2 Nov 2026.
A benchmarking platform that lets you create custom evaluations using your own tasks and data, then run frontier models against them to compare performance
The story so far
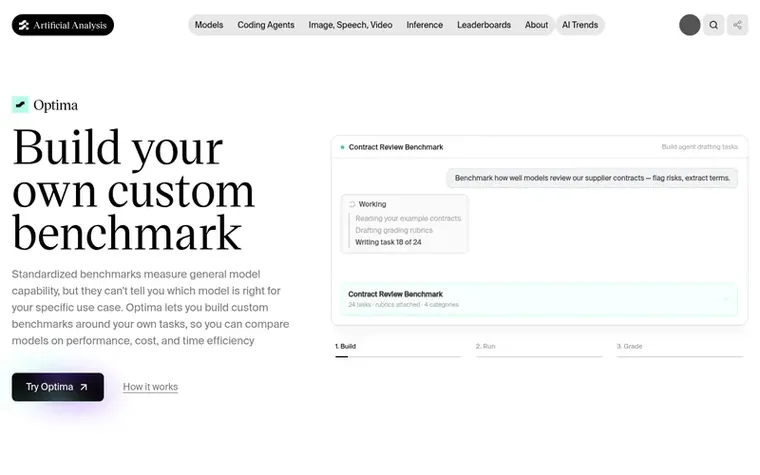
Homepage of Optima
Optima is a custom benchmarking platform that enables organizations to build their own evaluation frameworks tailored to their specific use cases. Unlike standardized benchmarks that measure general model capability, Optima lets you upload your own tasks, datasets, or agent trajectories and run them against frontier models to get performance results with detailed cost and time per task comparisons.
The platform supports multiple evaluation types including Q&A tasks with objective grading, document-based questions, agentic task completion with tools, and interactive conversations. You can grade results using custom rubrics or Artificial Analysis's panel of judges from major evaluations.
Optima handles the entire workflow: you describe your context and provide examples, the build agent helps draft tasks and rubrics with you, you select your evaluation type and models to run, and finally you receive graded results showing how each model performed against your criteria. Pricing is based on token usage for running benchmarks and per-criterion or per-match costs for grading, with no markup on raw model token costs.
Typeset features
Custom benchmark builder with example-driven task creation
Run benchmarks across multiple frontier models simultaneously
Cost and time per task metrics
Standard and premium judge tiers for grading
Rubric grading with custom criteria
Deterministic objective grading
No markup on model token costs
Pricing
Token usage for creating and running benchmarks at raw model cost. Rubric grading: $0.002 per criterion per model (standard judges) or $0.040 per criterion (premium judges), $0.10 on agentic tasks. Pairwise grading: $0.006 per match (standard, $0.150 premium), $0.015 per match on document tasks (sta
Optima metrics
Set in type for artificialanalysis.ai: Ahrefs Domain Rating and Majestic link data, with the change since the last edition.
Metric
Value
Domain Rating
84▼ −1 (down) since last check
Trust Flow
28● no change since last check
Citation Flow
59● no change since last check
Referring domains
17,353● no change since last check
External backlinks
1,067,004● no change since last check
Ahrefs Domain Rating set in type 2 Nov 2026, reset 2 Nov 2026. Lead topic: Society/People (24). Majestic set 1 Nov 2026, reset 1 Nov 2026. Link data typeset by Majestic. Trust Flow, Citation Flow and Topical Trust Flow are trademarks of Majestic-12 Ltd.
Optima domain colophon
Read the colophon
From the registry's public RDAP record, checked 2 Nov 2026, 20:56 UTC.
Measured after Optima went live on Zivaro Launch on 1 November 2026.
Domain Rating (Ahrefs)
84▼ −1 (down) since launch
85 at launch (1 Nov 2026), 84 on 2 Nov 2026
Referring domains (Majestic)
17,353
First measured 1 Nov 2026
Day 1 since launch. Next receipt: day 30, 1 Dec 2026. These are measurements, not proof of cause: many things move these numbers. Figures we have not measured are left out.
Optima supports Q&A with objective grading, document input where models answer questions about uploaded files, agentic tasks where models complete deliverables using tools, interaction simulations with different user types, and rubric-only grading.
How is pricing calculated?
Creating and running benchmarks is charged at the raw token cost of the models used with no markup. Grading is priced per criterion for rubric grading ($0.002 standard, $0.040 premium, $0.10 for agentic) or per match for pairwise grading ($0.006-$0.045 standard, $0.150 premium depending on task type).
Can I run my own agent in Optima benchmarks?
Yes, your own agent can compete in the same benchmark run as frontier models through an HTTP interface, allowing you to compare it directly against other models.
Leave a review for Optima
No review of Optima set in type yet. Set the first.

 Accessia
 Tawa Guard
 orbench
 Libretto